
|
|
NTileAggBucket |
N,Field,Aggregation Operations,Values Separator
Example: sales, views,amount
    Operation       Function
    -----------------------
    Max             maximum value
    Min             minimum value
    Sum             total value
    Average         average value
    Count           amount of data
Example:
Max:Min:Sum:Average:Count
Default: ,
Can be changed, for example:
|
    bucket
    values
    emp_name        dealer_id   sales
    ----------------------------------
    Kameko French   2       16233
    Ursa George     3       15427
    Ferris Brown    1       19745
    Noel Meyer      1       19745
    Abel Kim        3       12369
    Raphael Hull    1       8227
    Jack Salazar    1       9710
    May Stout       3       9308
    Haviva Montoya  2       9308
Group And Sort
    Grouped Field       :dealer_id
    Sorted Field        :sales (ascending)
Processed with NTileAggBucket, partitioned by dealer_id, ordered by sales, and using parameter :3,sales,MaxThe output of NTileAggBucket Buffer (field dealer_id, bucket, values) :
    dealer_id   bucket  values
    ---------------------------
    1	1           9710.0
    1	2           19745.0
    1	3           19745.0
    2	1           9308.0
    2	2           16233.0
    3	1           9308.0
    3	2           12369.0
    3	3           15427.0
3,sales,Max:Min:Sum:Average:CountThe output of NTileAggBucket Buffer (field dealer_id, bucket, values) :
    dealer_id   bucket  values
    -----------------------------------------------------
    1           1	9710.0,8227.0,17937.0,8968.5,2
    1           2	19745.0,19745.0,19745.0,19745.0,1
    1           3	19745.0,19745.0,19745.0,19745.0,1
    2           1	9308.0,9308.0,9308.0,9308.0,1
    2           2	16233.0,16233.0,16233.0,16233.0,1
    3           1	9308.0,9308.0,9308.0,9308.0,1
    3           2	12369.0,12369.0,12369.0,12369.0,1
    3           3	15427.0,15427.0,15427.0,15427.0,1
3,sales,Max:Min:Sum:Average:Count,|The output of NTileAggBucket Buffer (field dealer_id, bucket, values) :
    dealer_id   bucket  values
    -----------------------------------------------------
    1           1	9710.0|8227.0|17937.0|8968.5|2
    1           2	19745.0|19745.0|19745.0|19745.0|1
    1           3	19745.0|19745.0|19745.0|19745.0|1
    2           1	9308.0|9308.0|9308.0|9308.0|1
    2           2	16233.0|16233.0|16233.0|16233.0|1
    3           1	9308.0|9308.0|9308.0|9308.0|1
    3           2	12369.0|12369.0|12369.0|12369.0|1
    3           3	15427.0|15427.0|15427.0|15427.0|1
    Bucket	Meaning
    --------------------
    1           Low
    2           Medium
    3           High
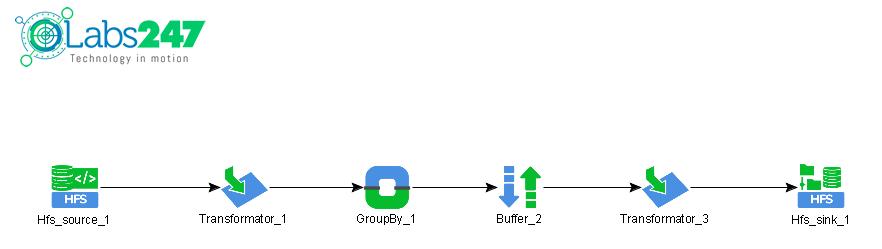
| Input Path | : | Arg[0] |
| File Type | : | Hfs |
| Combine Input | : | false |
| Fields in Lower Case | : | false |
| Delimiter | : |
| Input Field | Operation | Output Field | Type |
|---|---|---|---|
| line |
RegexSplitter(Splitter=|) |
emp_name dealer_id sales |
String String String |
| Input Field | Buffer Operation | Output Field | Type |
|---|---|---|---|
|
emp_name dealer_id sales |
NTileAggBucket(3,sales,Max:Min:Sum:Average:Count,|) |
emp_name dealer_id sales BUCKET Value |
String Integer Double Integer String |
| Input Field | Operation | Output Field | Type |
|---|---|---|---|
| dealer_id | No Operation | dealer_id | Integer |
| BUCKET | No Operation | BUCKET | String |
| Value | No Operation | Value | String |
| Fields Name | : | dealer_id, BUCKET,Value |
| Output Path | : | Arg[1] |
| Output Name | : | hgrid247-##### |
| Sink Mode | : | SinkMode.REPLACE |
| Partition Field(s) | : | |
| Splitter | : | |
| Index | : |